
Jev and the Falling Cost of AI Intelligence
Over the past year, the generative AI era has given software teams a new superpower: when you run into a difficult software or process problem, the answer is increasingly some version of, send it to a large language model.
That approach makes sense when the job is open-ended. General-purpose models are remarkably good at writing, explaining, summarizing, reasoning, and handling messy instructions. But a large share of the intelligence software needs is much narrower: Is this record in the right category? Does this text support this claim? Which of these choices best fits the evidence? Is the model confident enough to act without human review?
TypeSafe, a new company founded by members of the early OpenAI team, is betting that these kinds of problems deserve a different kind of model.
We wanted to see if that held up on real-world work.
Jev is built for decisions, not conversation
TypeSafe calls Jev its first System One Model, a new model architecture designed around fast decisions inside software rather than conversations with people. Instead of returning a paragraph or a string that software has to interpret, Jev returns one of the allowed structured answers, along with probabilities and, for certain question types, a confidence score.
That is a narrower job than a general-purpose language model performs. It is also the point.
Optimized for flexible language generation and reasoning across many kinds of tasks.
- Open-ended output
- Useful for writing and synthesis
- Sequential token generation
- Software often has to parse the response
Optimized for bounded decisions that can slot directly into a software workflow.
- Allowed outputs defined in advance
- Probabilities and confidence included
- Outputs generated in parallel
- Designed for classification, routing, scoring and verification
TypeSafe sometimes describes this as eliminating hallucinations. The important distinction is narrower: Jev cannot wander off-schema and invent a free-form response because free-form text is not an available output. It can still make the wrong judgment. TypeSafe's own guidance says developers need to measure accuracy and confidence on their actual workloads.
Why giving up generality can be an advantage
General-purpose models carry flexibility that many software decisions do not need. If a system only needs to choose among a few defined outcomes, generating a full response token by token can be an expensive way to get there.
TypeSafe built Jev around a different tradeoff: restrict the output space, make the decision in parallel, and optimize the training process for calibrated decisions rather than human-preferred prose. The input space is still general purpose and can make Jev applicable to an unlimited number of use cases without custom-built code (and IF statement can be replaced by intelligence!)
TypeSafe reports Jev response times of roughly 70 to 500 milliseconds and prices input at $0.042 per million tokens, with output too inexpensive to meter. In its own workflow evaluations, the company reports much larger speed and cost advantages over frontier LLMs. Those are TypeSafe's benchmarks, and the company notes that the exact advantage depends heavily on the workload and comparison method.
We gave Jev a real-world test at CarGenius
CarGenius does a substantial amount of data processing and AI-driven analysis across our products. That gave us a useful testing ground: workloads we already understand, existing methods to compare against, and enough real data to see where a new approach succeeds or fails.
We tested Jev on ten kinds of judgment tasks using the same underlying inputs as our existing methods. We also created independent answer keys so the comparison was not simply a measure of whether Jev agreed with what we already did.
The economics may be the more important result
Better accuracy is useful. Better accuracy at a radically lower cost changes what software can economically afford to do.
One of our test workloads involved roughly 390,000 input tokens of repeated judgment work. At the prices we used for the evaluation, the same input would cost about two cents with Jev, roughly 40 cents with a small general-purpose model and about $1.20 with a larger model. The language-model estimates also exclude the additional cost of generated output, so they are conservative.
Estimated Jev input cost for a roughly 390,000-token batch of narrow decision checks.
This is a workload-specific comparison, not a universal claim about model costs.
Two cents versus a dollar is not interesting because it saves a dollar. It is interesting because repeated checks that once seemed too expensive or slow to run everywhere can become cheap enough to make routine.
That is a different kind of product change. Once the marginal cost of a useful judgment gets close enough to zero, developers can start asking for far more of them.
The cost of useful intelligence keeps falling
There is no established Moore's Law for AI intelligence. Model capabilities, hardware, training methods and inference economics do not improve on one clean schedule. But the direction of travel is hard to miss.
Stanford's 2025 AI Index found that the cost of reaching roughly GPT-3.5-level performance on the MMLU benchmark fell from $20 per million tokens in November 2022 to $0.07 by October 2024. Epoch AI found that the pace varies dramatically by task, but the broad trend is steeply downward.
Jev is a different mechanism for pushing that curve. Instead of making a general-purpose model cheaper, it asks whether some workloads should use a different architecture in the first place.
That is also why TypeSafe named the model after economist William Stanley Jevons. Jevons paradox describes a counterintuitive pattern: making a resource more efficient can increase its total consumption because new uses become economical. TypeSafe's bet is that machine intelligence can behave the same way.
Specialized models may become another layer of the AI stack
It is too early to know whether Jev itself will become widely adopted, although based on our early testing, it looks likely to become part of our products and internal processes at CarGenius AI. TypeSafe only released it in early access this month. The more interesting question is whether the underlying architectural idea spreads.
There are several plausible paths, and they can all point in the same direction.
Specialists take specific workloads
Models like Jev handle repetitive, bounded decisions while larger models remain responsible for reasoning, synthesis and generation.
Frontier labs absorb the idea
Major model providers may add similarly optimized decision capabilities, routing more requests to cheaper internal architectures when a full LLM is unnecessary.
Hybrid systems become normal
Software increasingly combines traditional code, specialized AI and general-purpose models, choosing the least expensive tool that can reliably do each part of the job.
The common denominator is not Jev. It is the unbundling of intelligence. Developers may stop asking which single model should run an application and instead ask which kind of model should handle each decision.
What CarGenius takes from the experiment
For CarGenius, the practical lesson is straightforward. We will continue testing specialized models where they improve the economics or reliability of AI-driven work, while keeping general-purpose models for the jobs that actually need their flexibility.
But the larger takeaway extends well beyond automotive retail. Our Jev tests gave us a small real-world example of what happens when a useful form of intelligence gets both better and cheaper at the same time.
If specialized architectures can keep pushing down the cost of reliable decisions, AI will move into parts of software where today's economics still do not work. Some of those applications will look obvious in hindsight. Others probably have not been invented yet.
That is what makes Jev interesting to us. The model itself is new. The larger possibility is much bigger.
See what AI says about your dealership
CarGenius Dealer AI Visibility Reports measure which dealerships AI assistants actually name when shoppers ask non-branded Find, Buy, and Service questions, which competitors win those recommendations, and which sources are shaping the answers. See where your store stands.
View the Visibility ReportsGet a Custom ReportOr book a demo →Sources and methodology
- TypeSafe: Introducing System One Models & Jev, September 15, 2026. Source for TypeSafe's model architecture, pricing, latency, workflow benchmark claims and the Jevons-paradox naming rationale.
- TypeSafe documentation: Introduction and related documentation on structured questions, probabilities and confidence.
- The Rundown AI: TypeSafe launches Jev for AI decisions inside software, September 16, 2026. Independent summary of TypeSafe's claims and limitations.
- Stanford HAI: 2025 AI Index, Research and Development. Source for the decline in inference price at fixed performance levels.
- Epoch AI: LLM inference prices have fallen rapidly but unequally across tasks, March 12, 2025.
- CarGenius internal evaluation: September 2026 testing across ten types of narrow judgment workloads. Samples varied by test, with difficult cases intentionally overrepresented in several comparisons. The evaluation was designed to test Jev on real CarGenius workloads, not to produce a general benchmark of Jev or other models.
Jev and the Falling Cost of AI Intelligence
We tested TypeSafe's new decision model, Jev, on real CarGenius workloads. The results point to a future where specialized AI makes a much larger class of software automation practical.
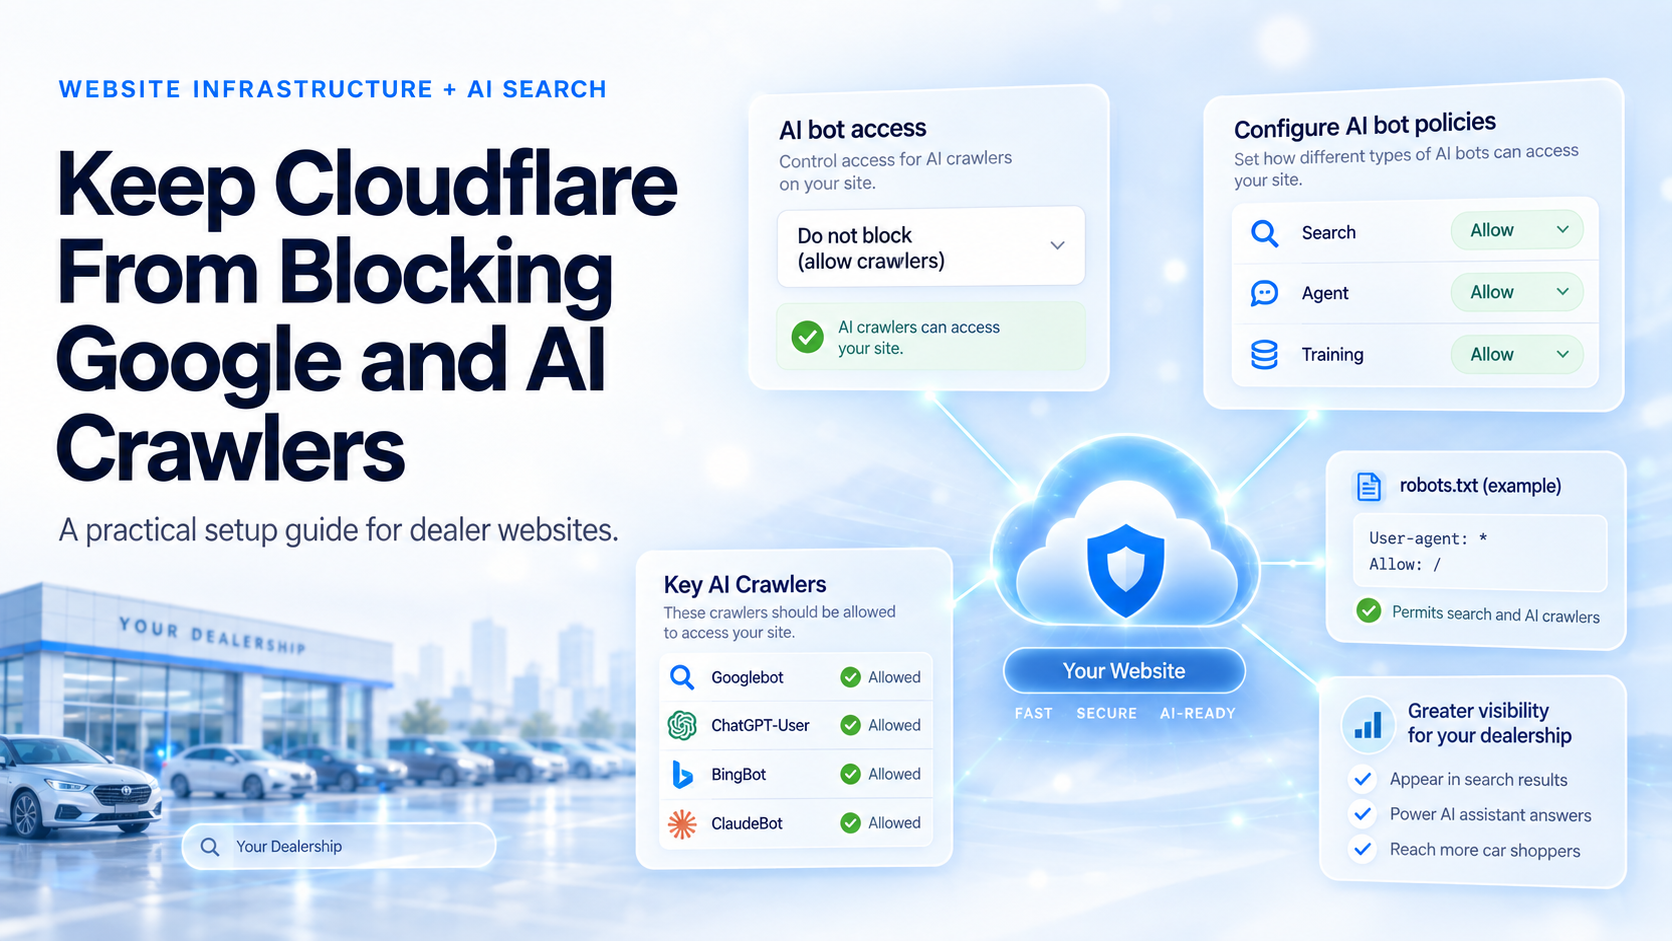
How to Keep Cloudflare From Blocking Google and AI Crawlers
Cloudflare now separates Search, Agent and Training crawlers. Here's how dealer website teams can preserve Google and AI search access while choosing their AI training policy.
of car shoppers now start with AI
higher conversion with AI search
instant answers for every shopper
Stay ahead of the curve
Get weekly insights on AI, automotive commerce, and dealer tech delivered to your inbox.